Key takeaways
- Promptwatch Data shows reddit.com's share of ChatGPT Search citations held at about 3.83% from July 18 to August 7, 2026, then fell below 1% on August 14. The August 14-17 average was 0.52%, an 86.4% relative drop.
- By the week of Sep 28 to Oct 4, Reddit was down to about 0.09% of ChatGPT citations. The drop did not bounce back.
- Google AI Overviews and AI Mode lost Reddit share only gradually, so this was mostly a ChatGPT event.
- The cause is not confirmed by first-party data. A robots.txt block and a ChatGPT retrieval change are both being discussed, and I'll separate what's measured from what's claimed.
- The practical answer is to stop treating Reddit threads as a ChatGPT channel and put the effort into your own site, plus the formats ChatGPT still cites.
What actually happened
For most of 2026, Reddit was one of the most reliably cited domains in ChatGPT Search. In April it was reportedly the single most-cited domain at about 4.14% of citations. Then, in a few days in August, it nearly disappeared.
Promptwatch tracked the daily share, and the shape of the chart is the story. The data covers July 7 to August 17, 2026, and you can read it in Promptwatch's Reddit citations report.

| Date | Reddit share of ChatGPT citations | What changed |
|---|---|---|
| Jul 18 to Aug 7 | ~3.83% average | Steady baseline |
| Aug 8 | High 3s down to mid 2s | ChatGPT's fanout behavior changed |
| Aug 14 | Below 1% | The cliff |
| Aug 14 to 17 | 0.52% average | 86.4% relative drop |
| Sep 28 to Oct 4 | ~0.09% | Still gone, per the October social citations report |
One caveat from the report itself: the size of the drop was labeled provisional at publication, and a data-collection issue could not be ruled out. The October follow-up, which shows Reddit still near zero seven weeks later, makes a measurement glitch far less plausible. Only responses with at least one citation count toward these shares.
The two-step timeline: August 8 and August 14
The drop had two stages, and they matter.
On August 8, ChatGPT Search started using the site: operator at scale. According to Promptwatch's site: operator report, site: queries went from 0.37% to 16.8% of all fanout queries overnight, about 46 times more. Average fanout queries per response rose from roughly 1.08 to 1.83 and stayed there. Reddit's share started sliding that same day.
Then on August 14 came the cliff. Same trend, different magnitude. That is why I'd resist any single-cause story. Something about how ChatGPT retrieves and selects sources changed on August 8, and something else, or a second phase of the same thing, finished the job six days later.
What it looked like on other platforms
Google's surfaces behaved very differently. Per the same Promptwatch report:
- Google AI Overviews: Reddit averaged 2.37% in the first 7 days of the window and 2.10% in the last 7, an 11.3% relative decline with no cliff.
- Google AI Mode: 2.22% down to 1.54%, a 30.5% relative decline, with the clearest step at the end of July.
So if your Reddit strategy was aimed at Google, nothing broke. If it was aimed at ChatGPT, it did.
The explanations, ranked by how much I trust them
There are four theories floating around. I'm sorting them by evidence, not by how good they sound.
1. A retrieval change in ChatGPT (plausible, correlated)
The timing of August 8 lines up with the site: operator rollout, and ChatGPT's search behavior clearly changed. Coverage in Forbes (citing Gizmodo and Promptwatch data) framed it this way. What's missing is a direct mechanism. OpenAI didn't announce anything, so the link is a correlation in time, not a proven cause.
2. Reddit blocked crawlers via robots.txt (claimed, unverified)
A post on explainx.ai says Reddit deliberately disallowed its whole domain in robots.txt, and that old.reddit.com added a mandatory login the same week. That would explain an overnight cliff neatly. But Promptwatch's report does not confirm a cause, and I have not been able to verify the robots.txt claim independently. Treat it as a third-party claim.
It's also worth knowing the explainx piece says Reddit had already been tightening access: more account bans, spam-heavy subreddits deleted, stricter anti-bot measures. That part is consistent with years of Reddit behavior, but again, it's their account.
3. A broad re-weighting toward first-party sources (third-party data)
An analyst named Ira Bodnar reportedly compared source mixes between model versions and found ChatGPT shifting toward vendor documentation, help centers and branded domains, away from forums and review sites. I can't verify that dataset. But it matches what Promptwatch's own category reports show: for software prompts, documentation and help centers earn the largest share, with GitHub, Microsoft's docs and G2 leading.
4. A recovery is coming (not supported)
The explainx post noted that a similar collapse in June 2026 reportedly recovered from under 1% to about 5% within two months, and suggested the same could happen here. I couldn't verify the June episode, and the October data does not show a recovery: Reddit sat at roughly 0.09% in early October. Don't plan around a comeback.
The bigger picture: ChatGPT has mostly left social
Reddit wasn't alone. In the October 2026 social media citations report, covering Sep 28 to Oct 4:
- All seven major social platforms together made up 0.46% of ChatGPT citations, down from 5.8% in the earlier report.
- Reddit went from 5.19% to 0.09%.
- LinkedIn became ChatGPT's most-cited social platform, at only 0.3%.
- Google AI Overviews got 12.2% of its citations from social platforms, about 26 times ChatGPT's share.
- Perplexity was at 2.7%, with LinkedIn and Reddit tied at 0.86%.
| Engine | Social share of citations | Notable platform |
|---|---|---|
| ChatGPT | 0.46% | LinkedIn, 0.3% |
| Google AI Overviews | 12.2% | YouTube 4.28%, Facebook 2.38%, Reddit 2.15% |
| Perplexity | 2.7% | LinkedIn and Reddit, 0.86% each |
That's the real postmortem finding. Reddit didn't lose out to another forum. Social as a source type nearly left ChatGPT.
Why a Reddit-only strategy was always fragile
I'll be blunt. Plenty of GEO advice in 2025 and early 2026 amounted to "post on Reddit and you'll show up in ChatGPT." It worked for a while, which made it feel like a system. It was a dependency on a platform you don't control, feeding a model you don't control, through a retrieval layer neither of them documents.
The lesson isn't that Reddit is dead. Reddit reports 500M+ weekly users, and it still earns citations in Google's AI surfaces. The lesson is that citation share on any one source can fall 86% in a week, and you will find out by watching a chart, not from an announcement.
Some of the community reaction was fair: one LinkedIn commenter called AI search a "constant moving target." The only sensible response is to diversify and measure.
What to do instead
Treat your own site as the primary retrieval surface
The site: operator shift makes this more pressing. If ChatGPT now runs about one in six fanouts as a domain-specific search, your domain needs to be crawlable, indexed and rich enough to answer when it does. Promptwatch's advice from that report is practical:
- Make sure key pages are crawlable and indexed. Thin category pages, broken internal search and unindexed content now cost you answers.
- Re-run fanout analyses, because keyword mappings built before August 8 are stale.
- Cover more angles per topic: comparisons, pricing, alternatives.
- Don't rewrite your whole content strategy before checking whether a platform-wide shift explains your numbers.
You can check crawler access quickly with Google Search Console for indexing and a crawler like Screaming Frog SEO Spider for site structure.
Publish the formats ChatGPT still cites
In Promptwatch's content type data (Sep 28 to Oct 4, 2026), product pages were the most cited type at 22.4%, followed by landing pages and listicles. And per the content half-life study, landing pages and docs stayed cited longest after July 6, while news lost half its pages within 36 days.
Put those together: durable pages beat timely ones. If you were using Reddit threads as a quick, disposable citation source, the replacement is documentation, comparison pages and product pages that you maintain.
Don't over-index on a single domain-rank assumption
Mid-authority sites did very well in ChatGPT in August. Promptwatch's domain rank report found DR 46-75 sites earned almost half of citations, while DR 91-100 fell to about 3%. You don't need to be a giant to get cited.
Match the platform to the channel
Promptwatch's own recommendations from the October report are a good starting point:
- For ChatGPT: stop relying on Reddit threads. Invest in your own site and the listicles, guides and comparisons it cites.
- For Google AI surfaces: YouTube first, then public Facebook and Instagram profiles.
- For Perplexity: publish on LinkedIn as well as Reddit.
- Keep X out of your AI search plans. It peaked at about 0.1% on Perplexity.
If you want the Reddit work to keep paying off, it still makes sense for Perplexity and Google, just not as a ChatGPT play. If you do engage on Reddit, do it as a genuine participant. The anti-spam crackdown described by third parties is a reason to avoid automation tools like ReplyAgent.ai for this purpose.
How to check your own exposure
Before changing anything, do the checks Promptwatch itself suggests:
- Compare the Reddit URLs cited before and after August 14. A broad loss across subreddits and topics points to a platform-level change. A narrow loss concentrated in a few topics points to something more specific, like a spam filter.
- Check your tracking for collection issues around August 14. A drop in response or citation volume can distort share numbers.
- Look at what replaced Reddit for your prompts. Which domains gained share tells you what ChatGPT now treats as authority for those queries: your docs, review sites, or competitors.
- Track citation share per AI engine separately. One universal explanation doesn't fit a ChatGPT cliff next to a gradual Google slide.
Tools that can run these checks
Dedicated platforms do this far faster than spreadsheets. Promptwatch is the one I'd start with, because it ties citation tracking to crawler logs and AI-referred traffic, so you see whether a lost source actually cost you visits, and its agents can draft and publish the content to fill the gap. Monitoring-only options exist too.
| Tool | Approach | Good for |
|---|---|---|
| Promptwatch | Tracking plus crawler logs, citation analytics, content gap analysis and a Content Agent | Teams that want to fix gaps, not just watch them |
| Otterly.AI | Prompt and citation monitoring | Budget-conscious tracking |
| Peec AI | Prompt tracking without optimization | Simple share-of-voice reporting |
| Profound | Enterprise monitoring | Large brands with bigger budgets |



For a broader list, the GEO software directory covers most options in the category.
Screenshots from the reporting
The explainx write-up that collected the early updates and third-party claims is where much of the robots.txt discussion started:
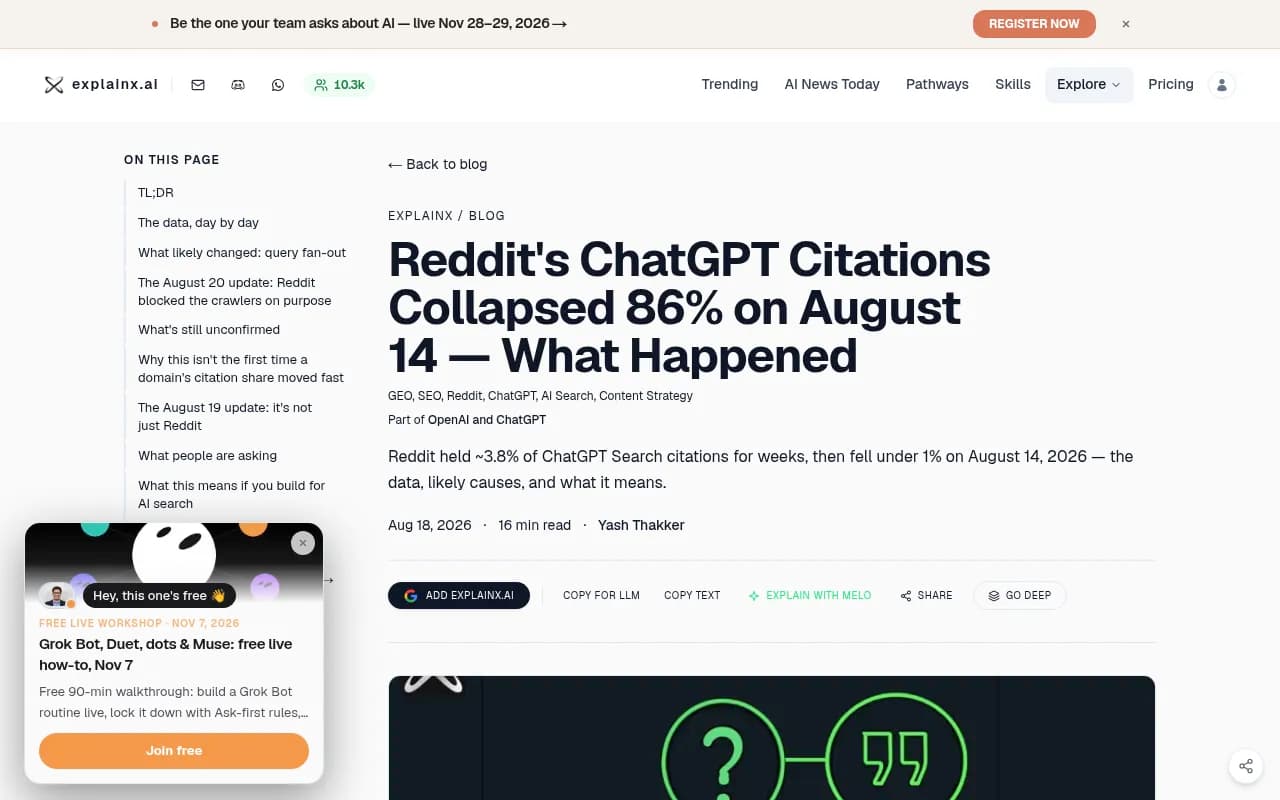
Read it with the caveat above: the Promptwatch report does not confirm its cause.
What I'd tell a marketing team on Monday
- Stop reporting Reddit mentions as a ChatGPT win. The citation channel is effectively closed for now.
- Audit your top 20 pages for crawlability and for the angles ChatGPT's extra fanouts now look for.
- Shift Reddit and community time toward Perplexity and Google, where it still gets cited.
- Add YouTube and LinkedIn to the plan, since they are the social sources still earning AI citations.
- Set up weekly citation share monitoring so the next 86% drop is a Tuesday-morning alert, not a quarter-end surprise.
If you want outside help building that kind of resilient AI search plan, agencies like 1001 SEO Media, which publishes this site, work on GEO alongside technical SEO and content.
Bottom line
Reddit went from about 3.8% of ChatGPT citations to roughly 0.09% in under two months, and the cause is still not publicly confirmed. What is confirmed is the pattern: ChatGPT now leans on your own domain and on durable, structured pages, and barely touches social. Build for that, measure by engine, and keep the full data set at Promptwatch Data bookmarked, because the numbers move monthly.